- Flow
- — cfs
- Water
- — °C
- Oxygen
- — mg/L
v0.2.0-rc.1 · MIT
Live state from Kafka to the browser. Never silently wrong.
StreamOtter is an open-source Node.js gateway and TypeScript browser SDK. Browsers subscribe to state channels, not raw Kafka topics: each view starts from a snapshot, updates in revision order, and says when it's stale. Your handlers decide who sees what.
Release candidate. The API may change before 0.2.0. What’s verified in this release →

DEMO · fictional creek, real Kafka pipelineConnecting to the field station…Lontra Creek field station
field instruments → Kafka → gateway
Your browserconnection connecting
- Where
- —
- Doing
- —
- Dives/hr
- —
- Stage
- — ft
- Turbidity
- — NTU
- Trend
- —
Try it: cut this page's connection. The creek keeps moving without you, and every view says it's stale until fresh snapshots arrive.
The live demo isn't answering right now. The field station's server may be restarting or down; the rest of this site works without it. You can run the same demo on your machine with Node.js 24 or later, no Kafka needed:
git clone https://github.com/jfricano/lontra-creek.git
cd lontra-creek
npm install
npm run devThen open http://127.0.0.1:4321. The demo's source is on GitHub.
A real StreamOtter subscription from this page to the Lontra Creek field station. Lontra Creek is a made-up river-otter study: the otters and the weather are simulated, and the data pipeline is real.
- MIT licensed
- Node.js 24 or later
- Socket.IO 4.8 transport
- Tested with Apache Kafka 4.1.2
0.2.0-rc.1on npm
How it fits together
Describe the state, protect it, subscribe to it
Browsers subscribe to state channels, not raw topics. You own identity, access rules, and the source of truth; StreamOtter owns synchronization, ordering, delivery, and recovery.
Describe the state
A channel names one piece of state, its parameters, and its schema. The gateway checks every payload against it, and
streamotter generateturns it into TypeScript types.{ "station": { "delivery": { "kind": "state", "overflow": "resync" }, "handlersRef": "station", "paramsSchema": "StationParams", "payloadSchema": "GaugeReading", "source": "field", "version": 1 } }Decide who sees it
Your handlers authenticate viewers, authorize each channel, pick state out of Kafka records, and read snapshots from your own store. Access is never guessed.
export const holt: HoltHandlers = {
  // Den sites are protected: only researchers may subscribe.
  authorize: ({ principal }) =>
    principal.claims["role"] === "researcher",
  // Pick this channel's state out of each Kafka record.
  map: ({ record }) => holtStates(record.value),
  // Read current state before releasing buffered updates.
  snapshot: ({ params, signal }) =>
    fieldStation.holt(params.holtId, signal)
};
Subscribe in the browser
The SDK hands you a snapshot, then every newer state in order, plus a state you can show. After a disconnect it resynchronizes from a fresh snapshot on its own.
const client = createClient<AppChannels>({
  getToken: ({ signal }) => session.token(signal)
});

const gauge = client.subscribe("station", {
  channelVersion: 1,
  params: { stationId: "LC-02" }
});
// A snapshot, then newer states in order.
gauge.on("data", event => render(event.data));
// Live, stale, resync-required…
gauge.on("state", ({ state }) => showState(state));
await gauge.ready();
Code samples are type-checked against [email protected].
No silent failures
Every view is in a state you can name
A view is never reported as live after a disconnect, a restart, or a slow connection. When something goes wrong, the state says what, and the error says what to do.
authorizing
Your handler is deciding whether this viewer may have this channel.
synchronizing
Loading a snapshot. Updates that arrive meanwhile are held, then released in revision order.
live
Caught up, with a healthy source. Show it as current.
stale
The connection or the source dropped. Keep showing the last state, marked stale, while StreamOtter recovers.
resync-required
Automatic recovery stopped after three tries. Offer a retry; resync() starts over.
failed
Refused or broken for good, like FORBIDDEN or invalid data. Replace the subscription.
In [email protected] · opt-in
Give a bad record a visible fate
Source-failure policies keep a bad Kafka record as evidence and let the stream move on only when your application can show its snapshots cover what that record would have changed. Without them, a bad record pauses its source, as before.
Preserve the record
A policy can copy the original record to a quarantine topic. Only a write Kafka acknowledged counts as saved; until then the source holds.
Continue only under control
Moving past the record needs your application's recovery guard to vouch for its snapshots. Otherwise the source stays held. There is no skip or ignore option.
See each outcome
Whether evidence was saved, whether the source advanced, and whether views resynchronized are reported separately. None stands in for another.
What this demo runs. Without a policy, a bad record pauses its source: it is never committed or skipped, views go stale, and resumeSource() retries the same record after a fix. The Failure Lab's Fouled sensor shows that on a leased bench, where the Lab is on. Its Source failures track lists the exercises built on the new policies, asks this demo's backend which of them it can run, and gives the reason for any it can't.
See it run
See it work, then see it break
What does it look like running?Field stationA guided walk down Lontra Creek in six short chapters: first light, a storm, a canyon with no signal, a protected den, a new person on the tablet, and your own sighting.What happens when it breaks?Failure LabBorrow an isolated bench for five minutes. Cut the relay, stall a laptop, restart the gateway, or foul a sensor, and follow each record through the gateway. The Source failures track lists the quarantine exercises and whether this demo's backend can run each one.What's it like to set up?PlaygroundEdit a streamotter.json and get the real validator's messages as you type, with nothing to install.What tools do I get?WorkbenchA tour of the local workbench: Connect, Define, Preview, Inspect, and Export.How does it fail, exactly?When it breaksEvery failure mode in this release: the state it produces, the error your code receives, whether it retries, and how to handle it. Plus the opt-in source-failure policies: quarantine, the recovery guard, and the operator commands.
Included with the CLI
See the contract and the state
Preview a channel with the real SDK, inspect its delivery state, and trace records through your local gateway.
Tour the workbench →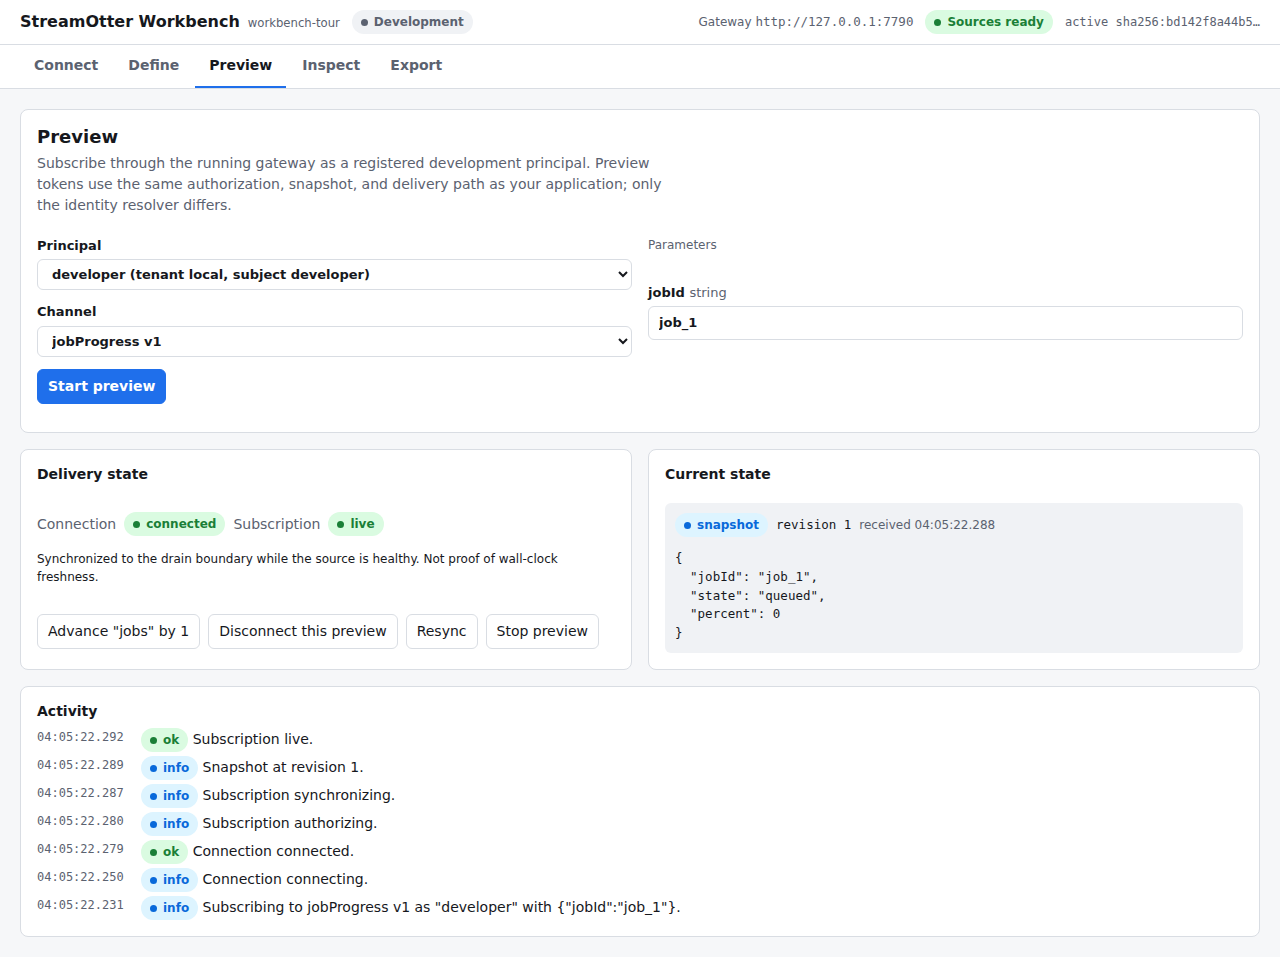
Recording · October 5, 2026 · [email protected] · local fixture project, not the hosted demo.
Five minutes, no Kafka needed
Try it on your machine
The scaffold uses a built-in fixture source. Open the workbench URL that dev prints, preview a channel, and advance the fixture to watch revisions arrive.
npm init -y
npm install [email protected]
npx streamotter init .
npx streamotter dev \
  --config streamotter.json --handlers server/handlers.mjs